CVPR 2025 modelIndependent evaluation
STT B
Reliability
Benchmark
A reproduction and reliability study of STT-B—testing whether fast, point-prompted segmentation holds up beyond a headline score.
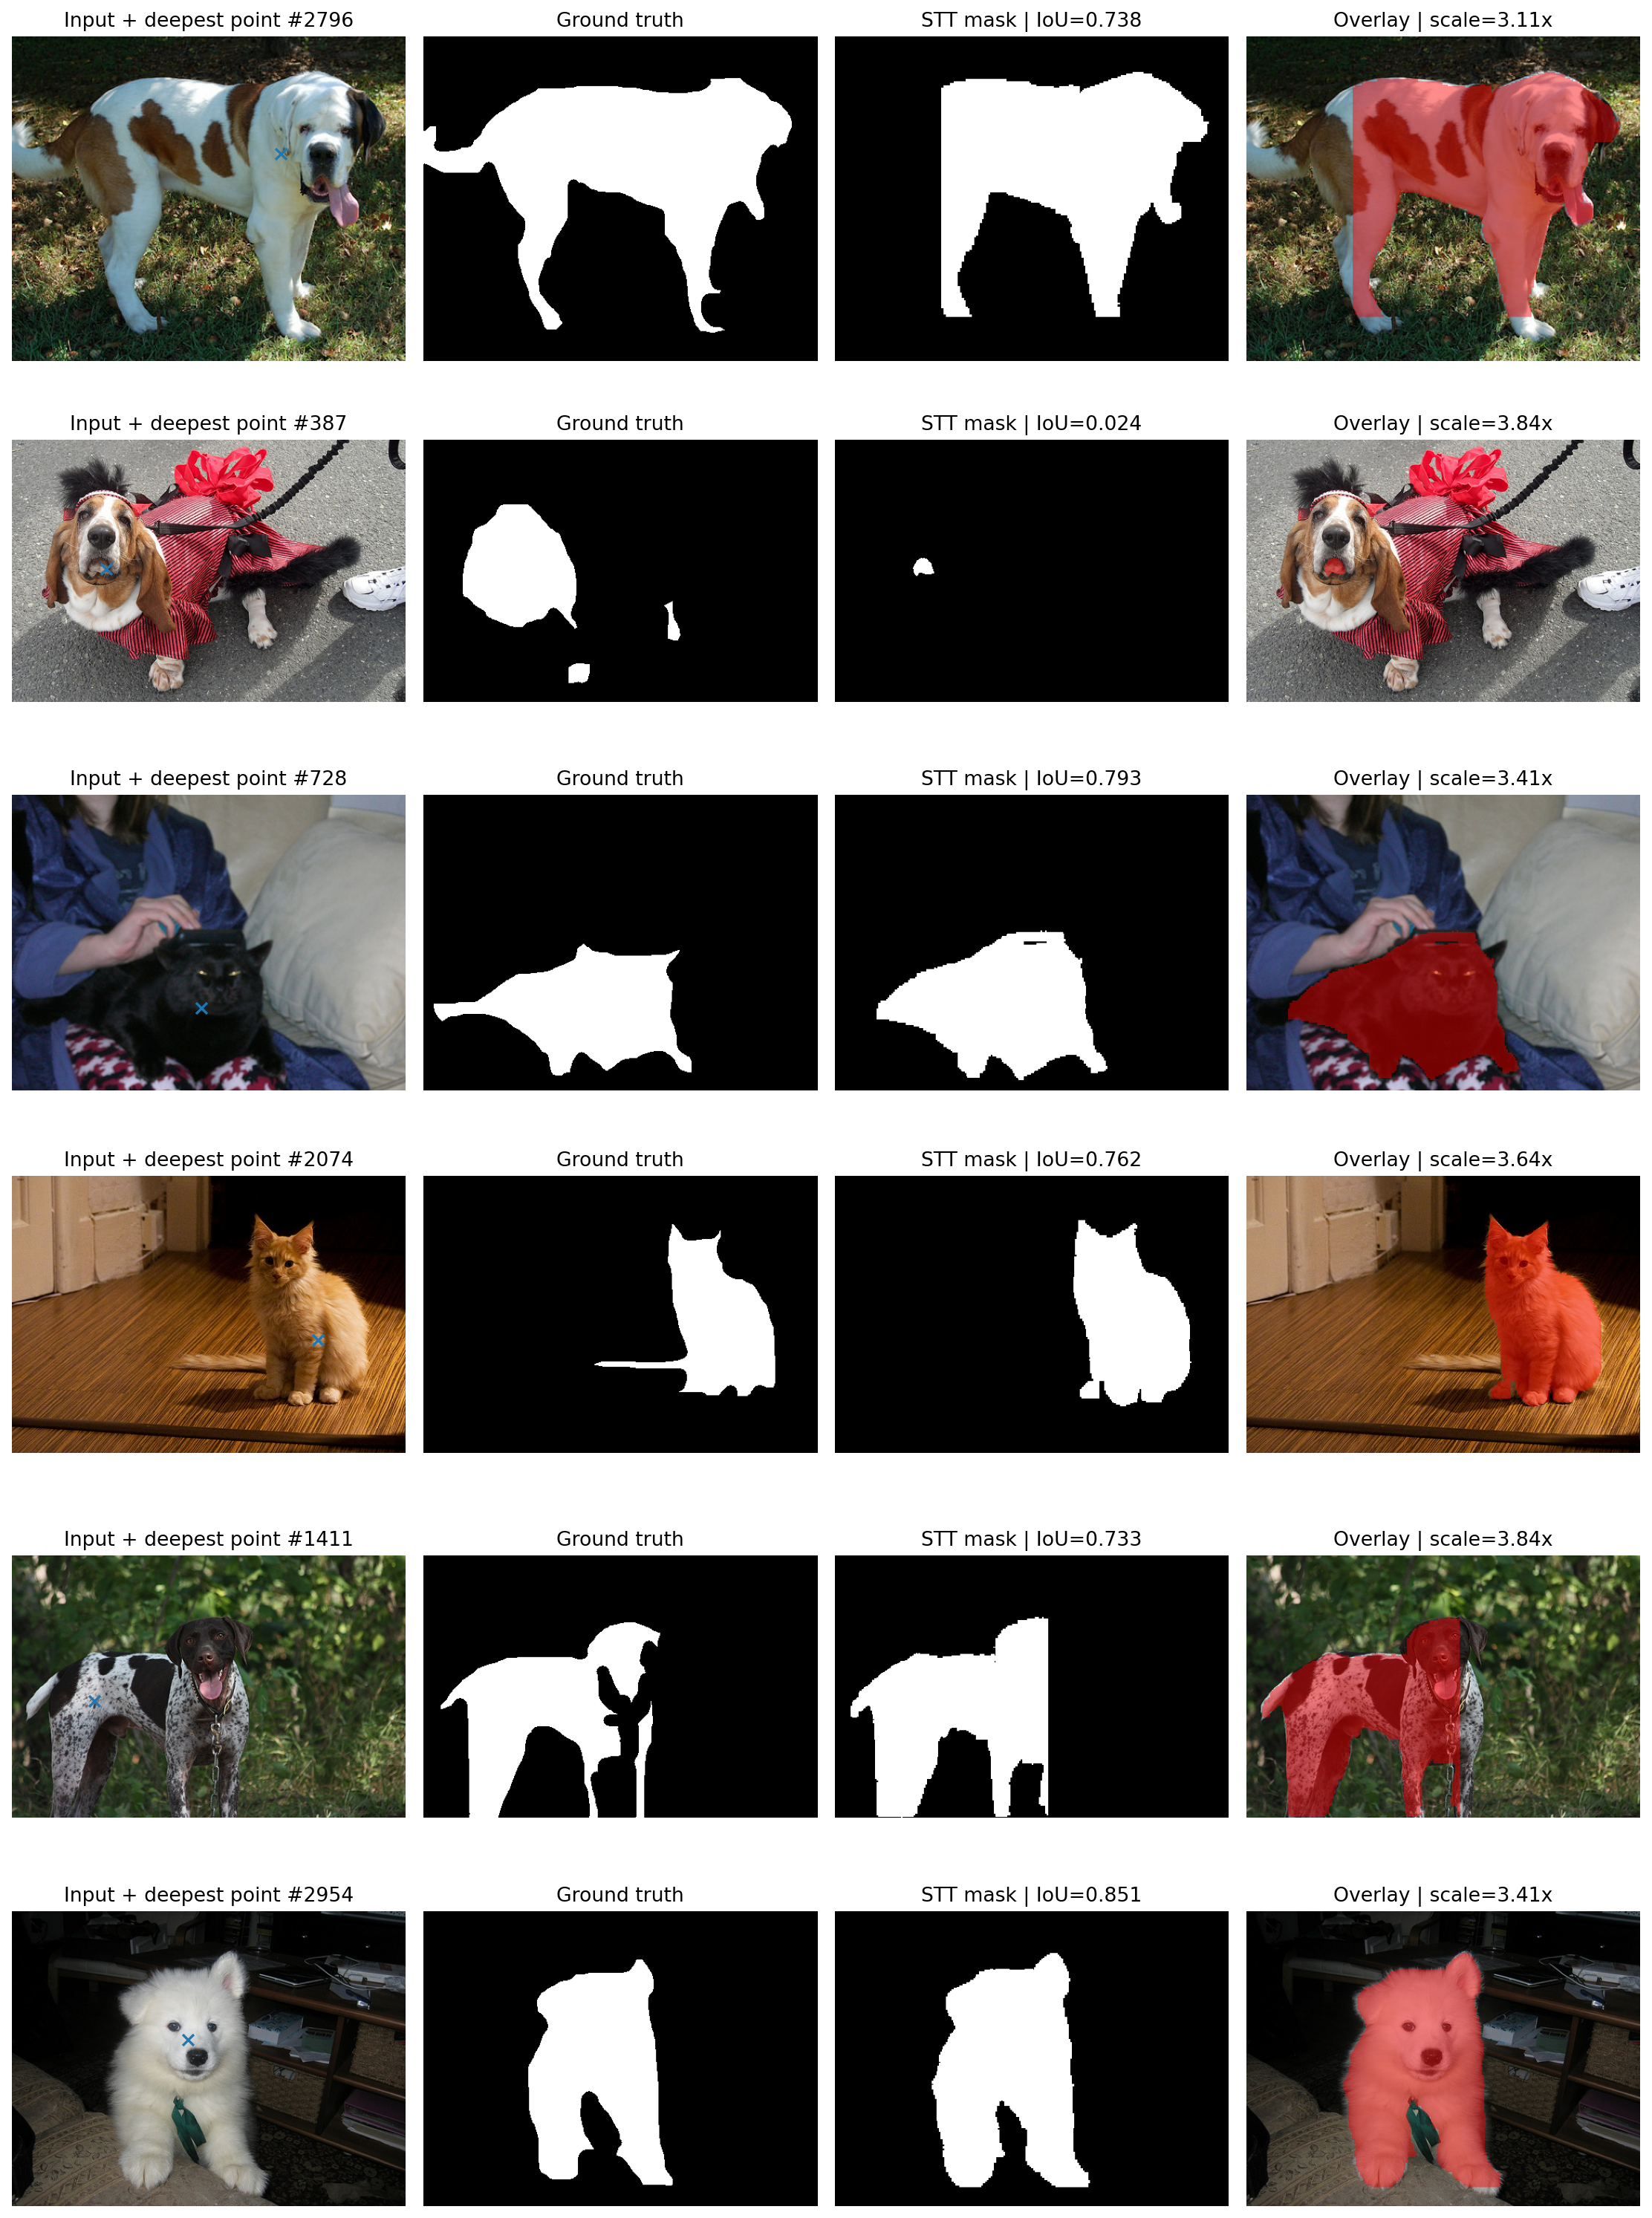
Point promptMask prediction
499images
evaluated
evaluated
One point.
One mask.
Seven dimensions of evidence.
The question
Fast segmentation is useful.
Reliable segmentation is better.
We evaluated the official STT-B checkpoint without retraining, then went further: prompt placement, image degradation, boundary quality, confidence calibration, failure cases, and a paired comparison against SAM ViT-B.
DatasetOxford-IIIT Pet
PromptDeepest interior point
HardwareNVIDIA Tesla T4
01
Primary results
Strong regions.
Imperfect edges.
↳
Precision exceeds recall, so STT-B more often misses part of the object than includes unrelated foreground. Region overlap alone hides the much weaker contour quality.
02
Paired comparison
STT-B vs.
SAM ViT-B
A clear quality–speed frontier.
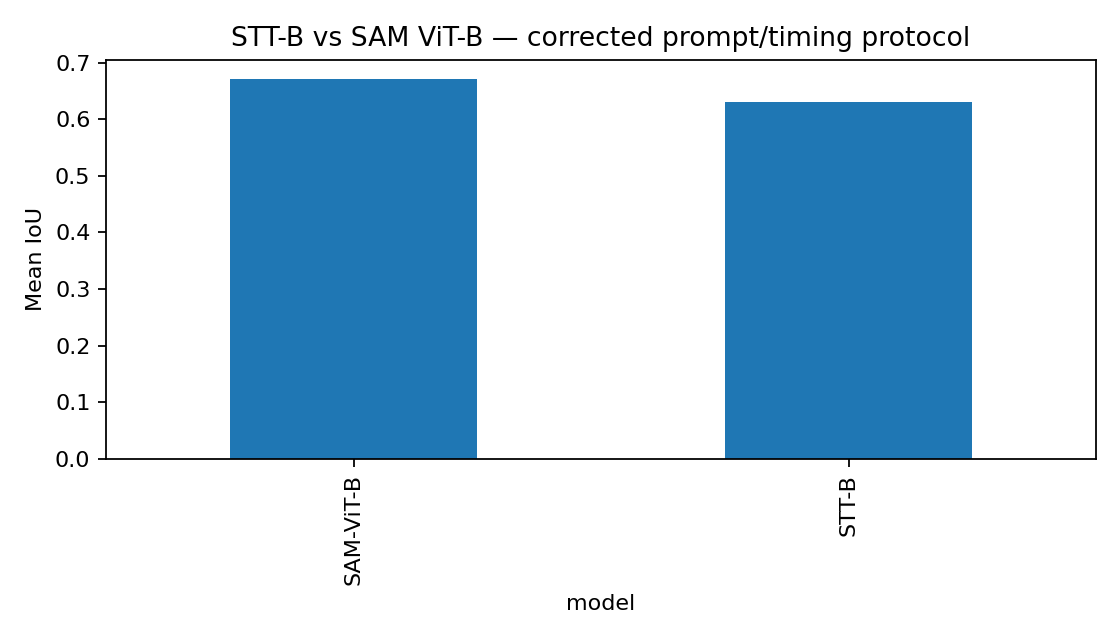
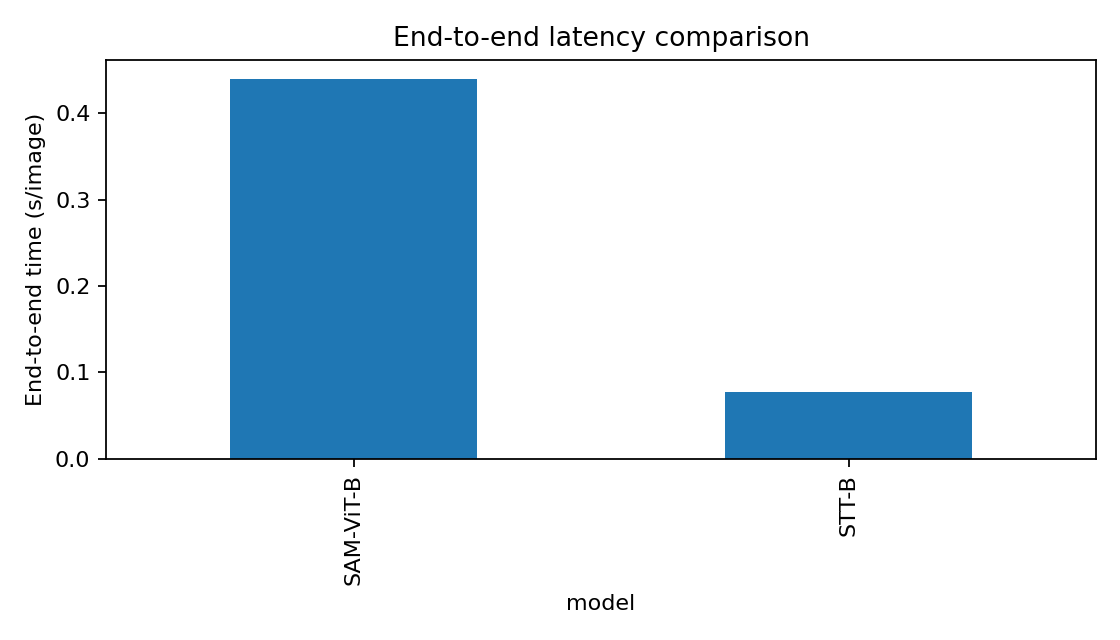
SAM produced moderately better masks on the same 100 images. STT-B answered much faster—making the choice less about a winner and more about the workload.
5.7×
faster end-to-end
than SAM ViT-B
than SAM ViT-B
MetricSTT-BSAM
Mean IoU0.6310.672
Recall0.7590.869
Latency77 ms440 ms
Throughput13.542.28 FPS
03
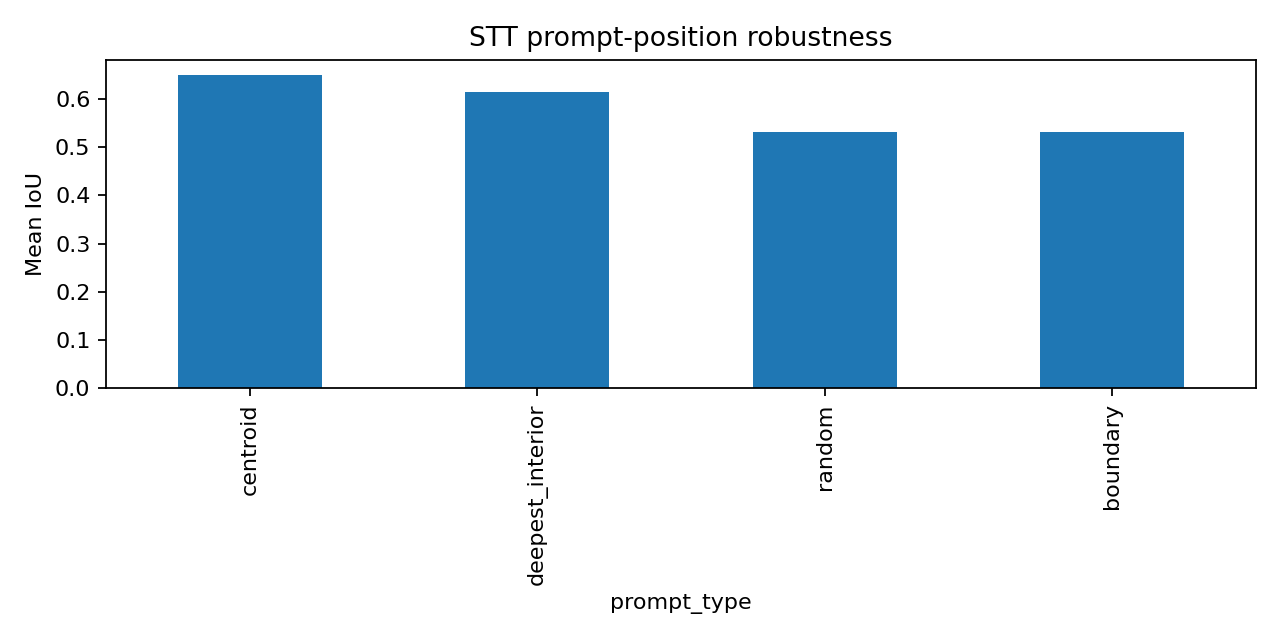
Stress tests
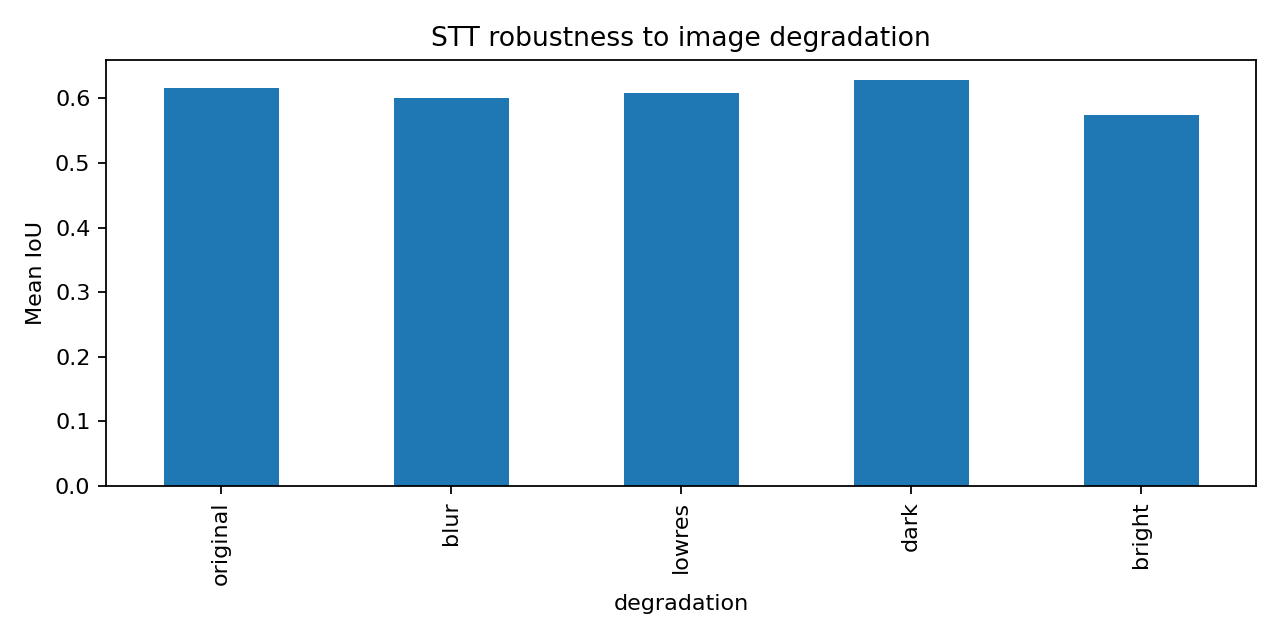
Small changes.
Material effects.
04
Reliability
Confidence is
not correctness.
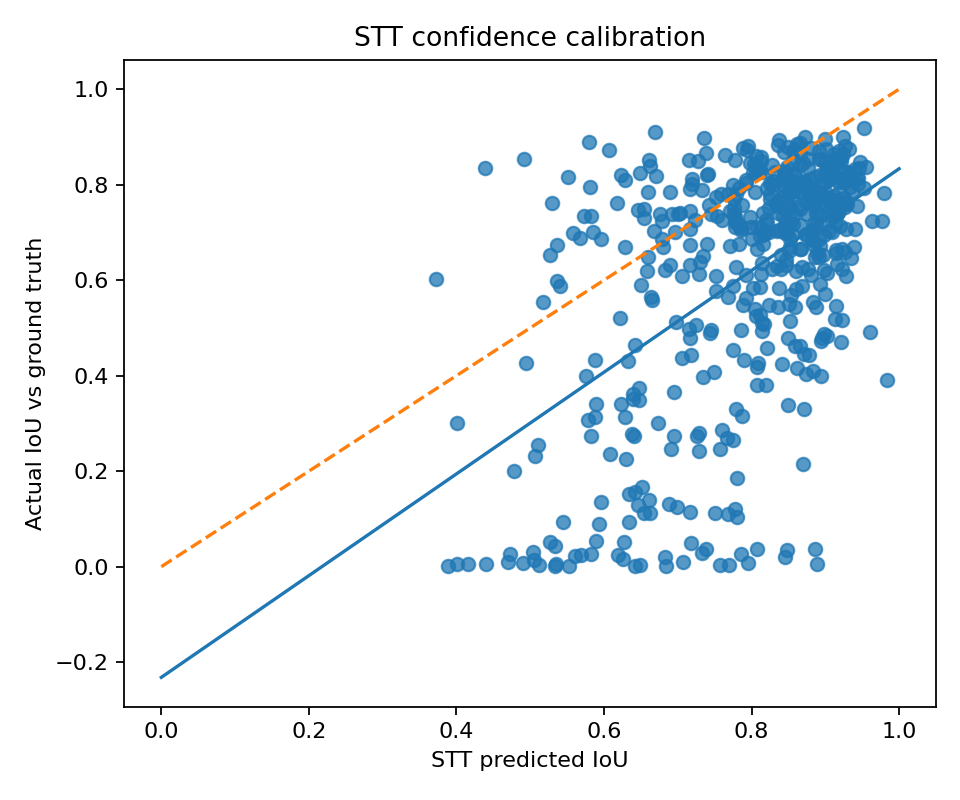
r = 0.518predicted vs. actual IoU
The model score is directionally useful, but the broad scatter makes it unsafe as a per-image guarantee.
66catastrophic failures
22high-confidence failures
05
Method
A fixed, reproducible
evaluation protocol.
- 01Sample
Shuffle the Oxford-IIIT Pet test split with seed 42 and request 500 valid masks.
- 02Prompt
Place one positive point at the deepest interior foreground pixel.
- 03Infer
Upscale the short side to 1,280 px, run STT-B, and map the prediction back.
- 04Measure
Score regions, boundaries, latency, GPU memory, geometry, confidence, and failures.
Reproduce the work